Welcome to byMAR.CO Engineering Blog 👋

I share learnings, experience and ramblings on modern AI developments. The posts are issued as concepts where a local LLM agent then performs further analysis and research for a comprehensive review of the initial thought.
Dark editorial graphic of a GPU die with one highlighted fuse array and two comparison bars labelled GeForce and Workstation, under the headline Half Speed By Fuse

NVIDIA Sells You Half a GPU: Inside the FP32 Accumulation Unlock

The gpu-unlock kernel modules lift NVIDIA’s half-rate FP32 accumulation cap on RTX 20, 30 and 40 series cards. The instruction rate doubles, the real-world gain is 10 to 20 percent, and the 4090 is the last card this works on. How the exploit works, what the benchmarks actually say, and why Blackwell closes the door.

October 27, 2026 · 13 min · 2674 words · Marco
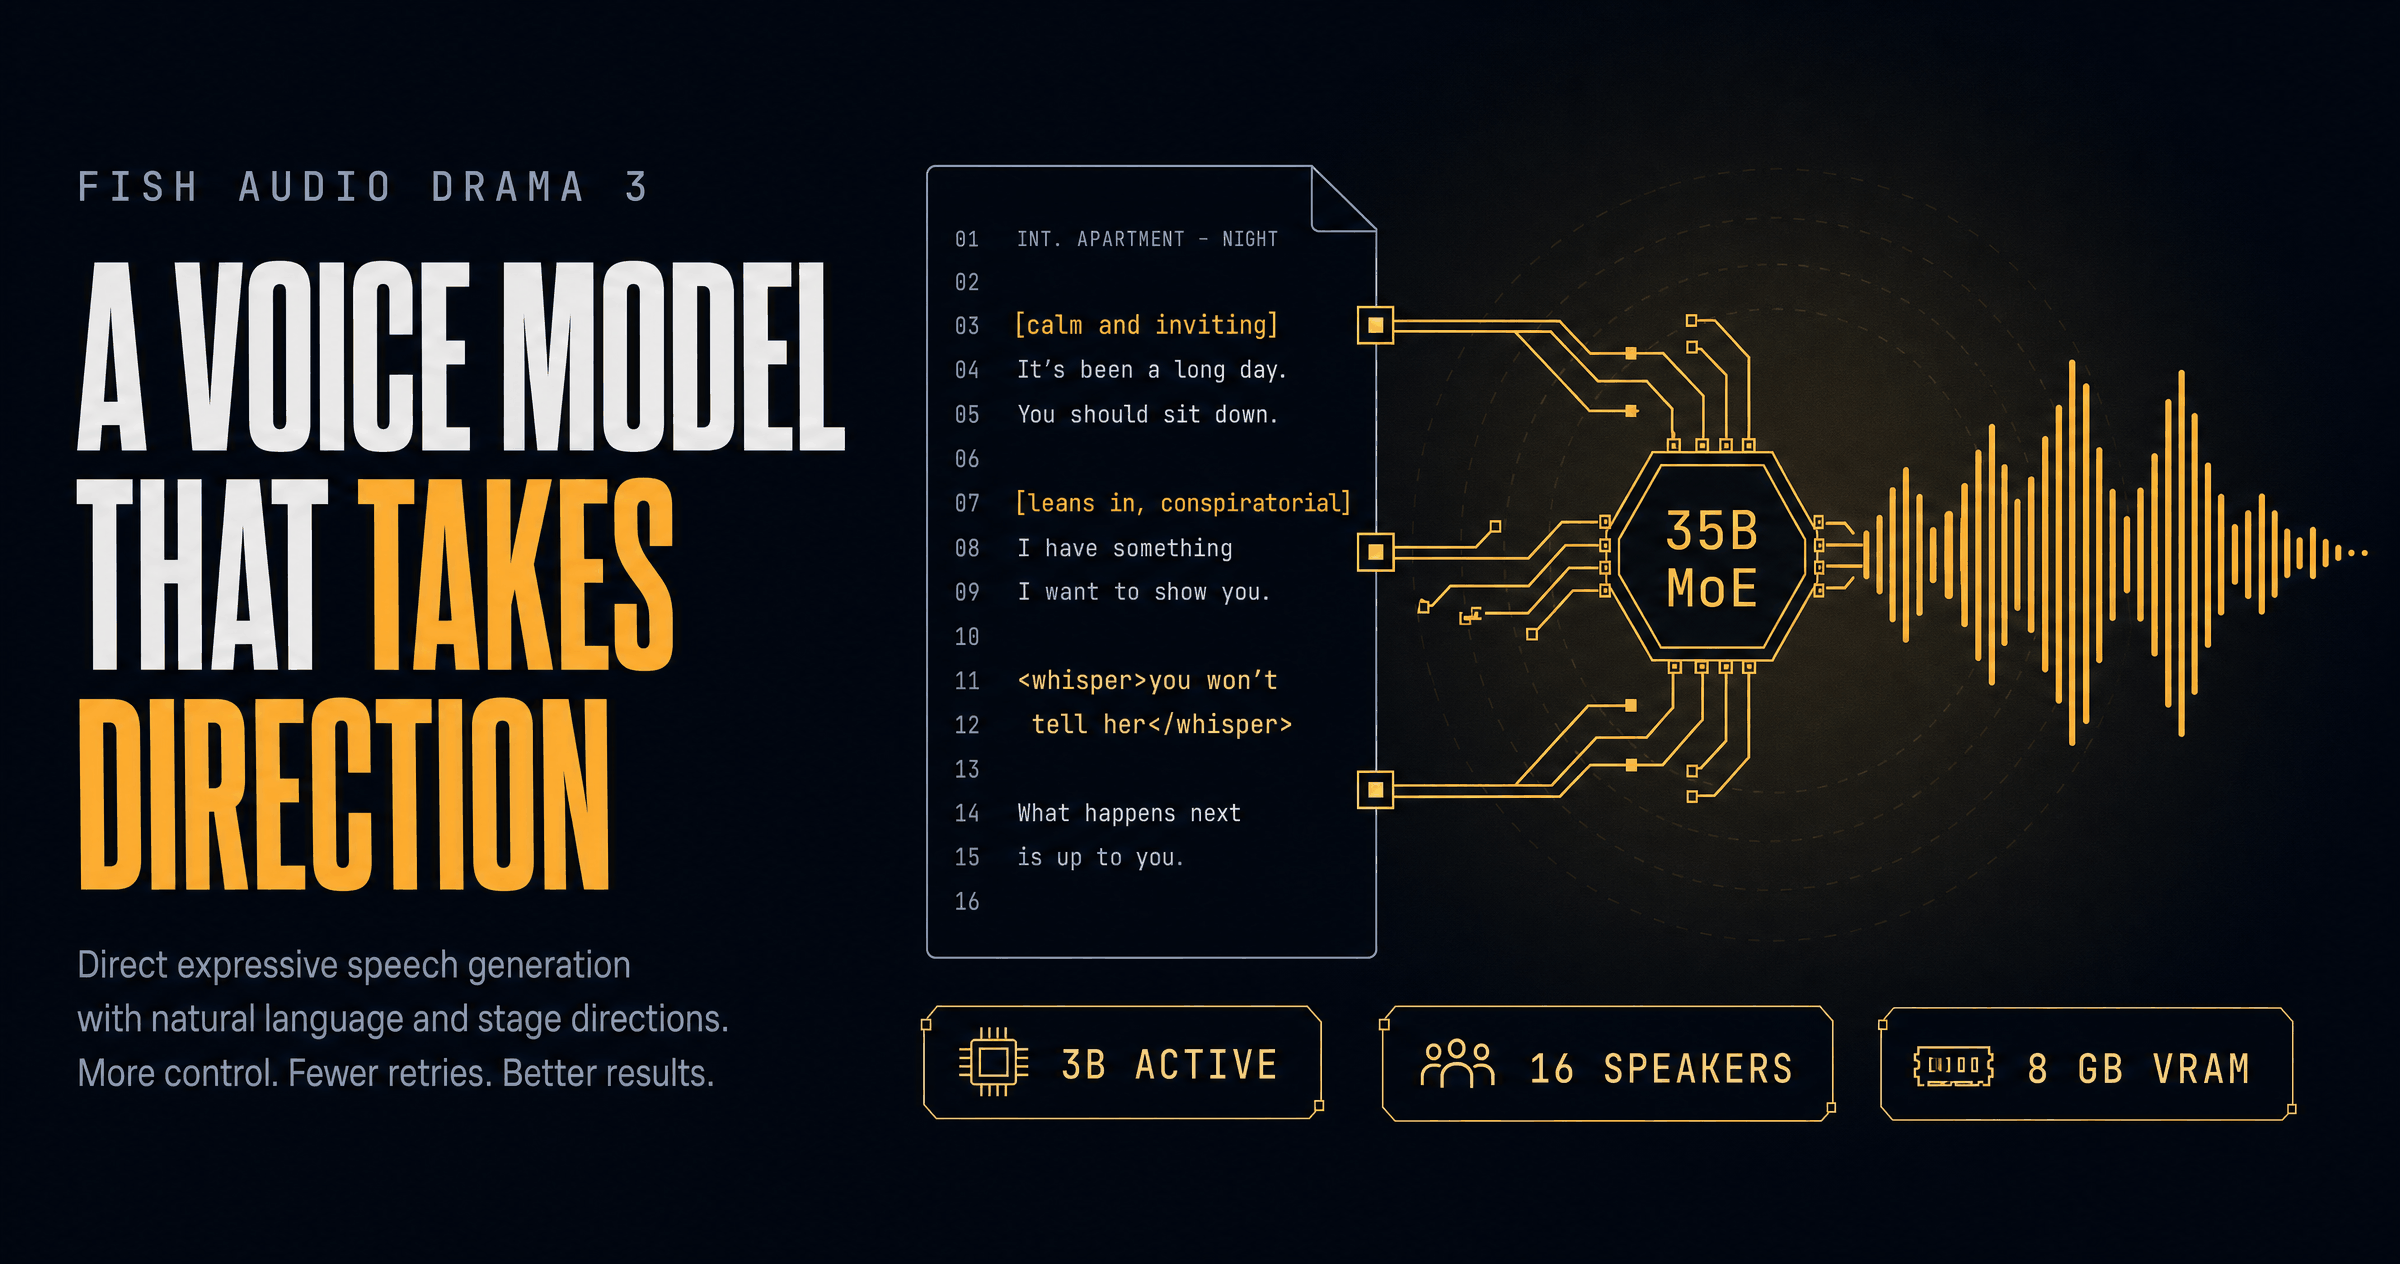
Dark editorial diagram of a screenplay page feeding through a 35B MoE chip into an audio waveform, labelled Fish Audio Drama 3

Fish Audio Drama 3: The First TTS Model You Direct Instead of Prompt

Fish Audio’s Drama 3 is a 35B MoE that acts instead of reading: free-text direction in brackets, word-scoped tags, 16 speakers, and retakes you can revise by note. How it works, how to run it locally in ComfyUI on 8 GB, and what the open-weight TTS race is doing to the market.

October 26, 2026 · 14 min · 2927 words · Marco
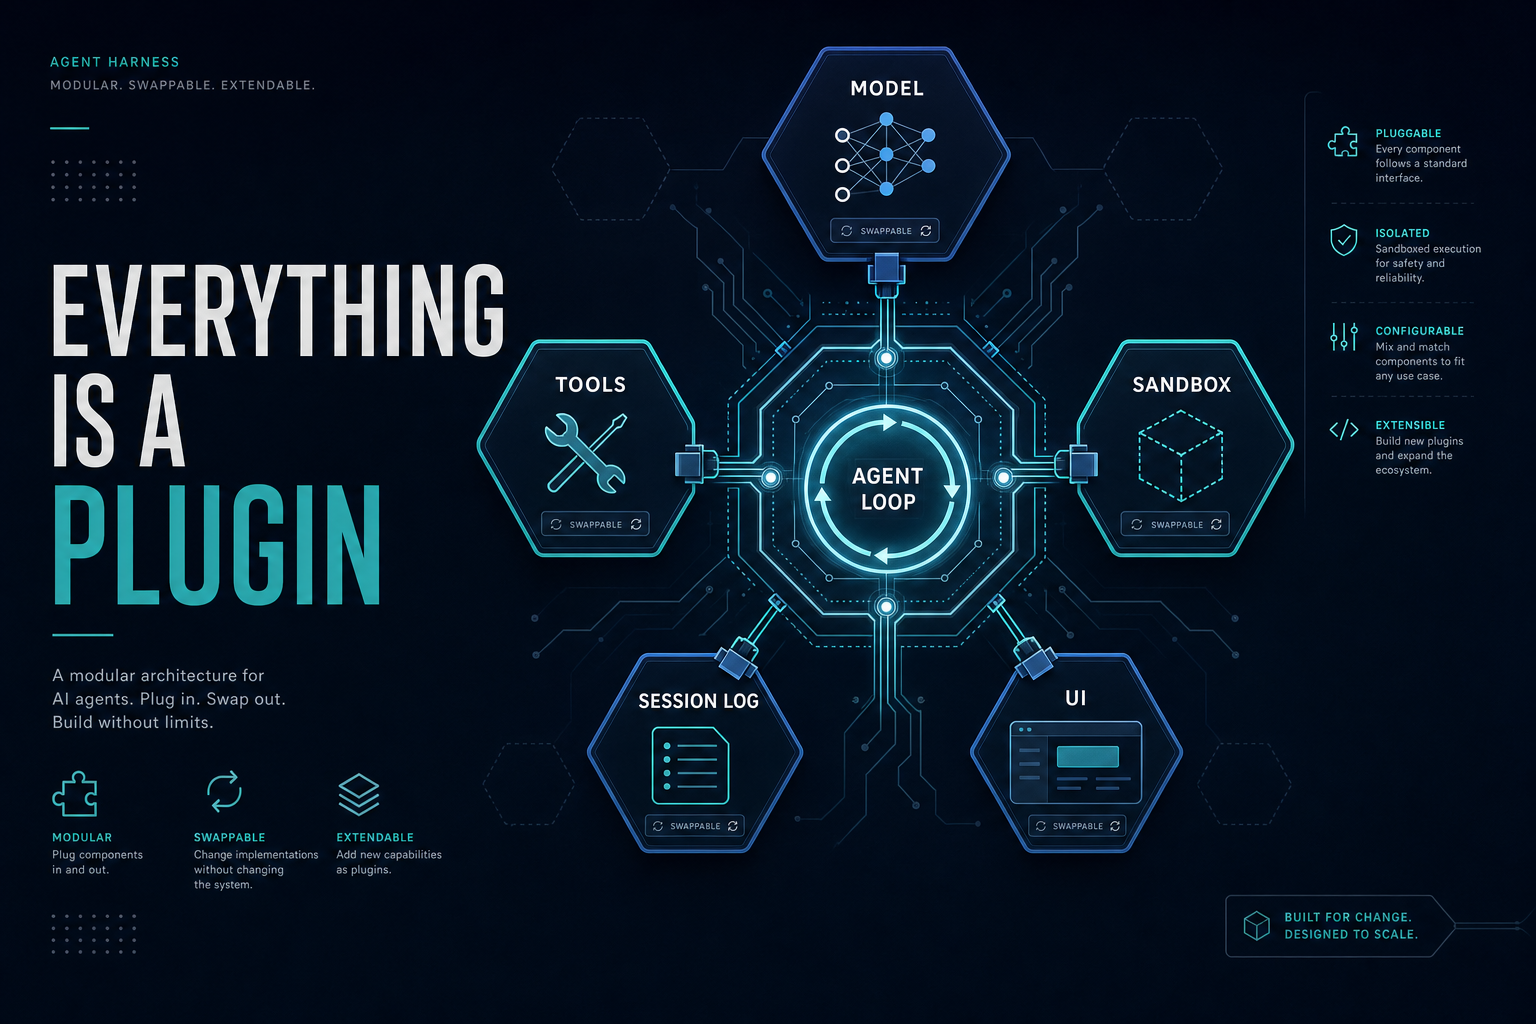
Modular diagram of the DeepSeek Harness plugin architecture: agent loop, model, tools, sandbox, and session log as swappable hexagon modules

DeepSeek Harness: The Agent Runtime Where Everything Is a Plugin

DeepSeek Harness hit 195K stars in two weeks. It’s less a coding agent than the machinery a coding agent gets assembled from: everything is a plugin, built on Cordis, with append-only session logs and subagents that can delegate to competitors. What’s real, what still hurts.

August 25, 2026 · 10 min · 1958 words · Marco
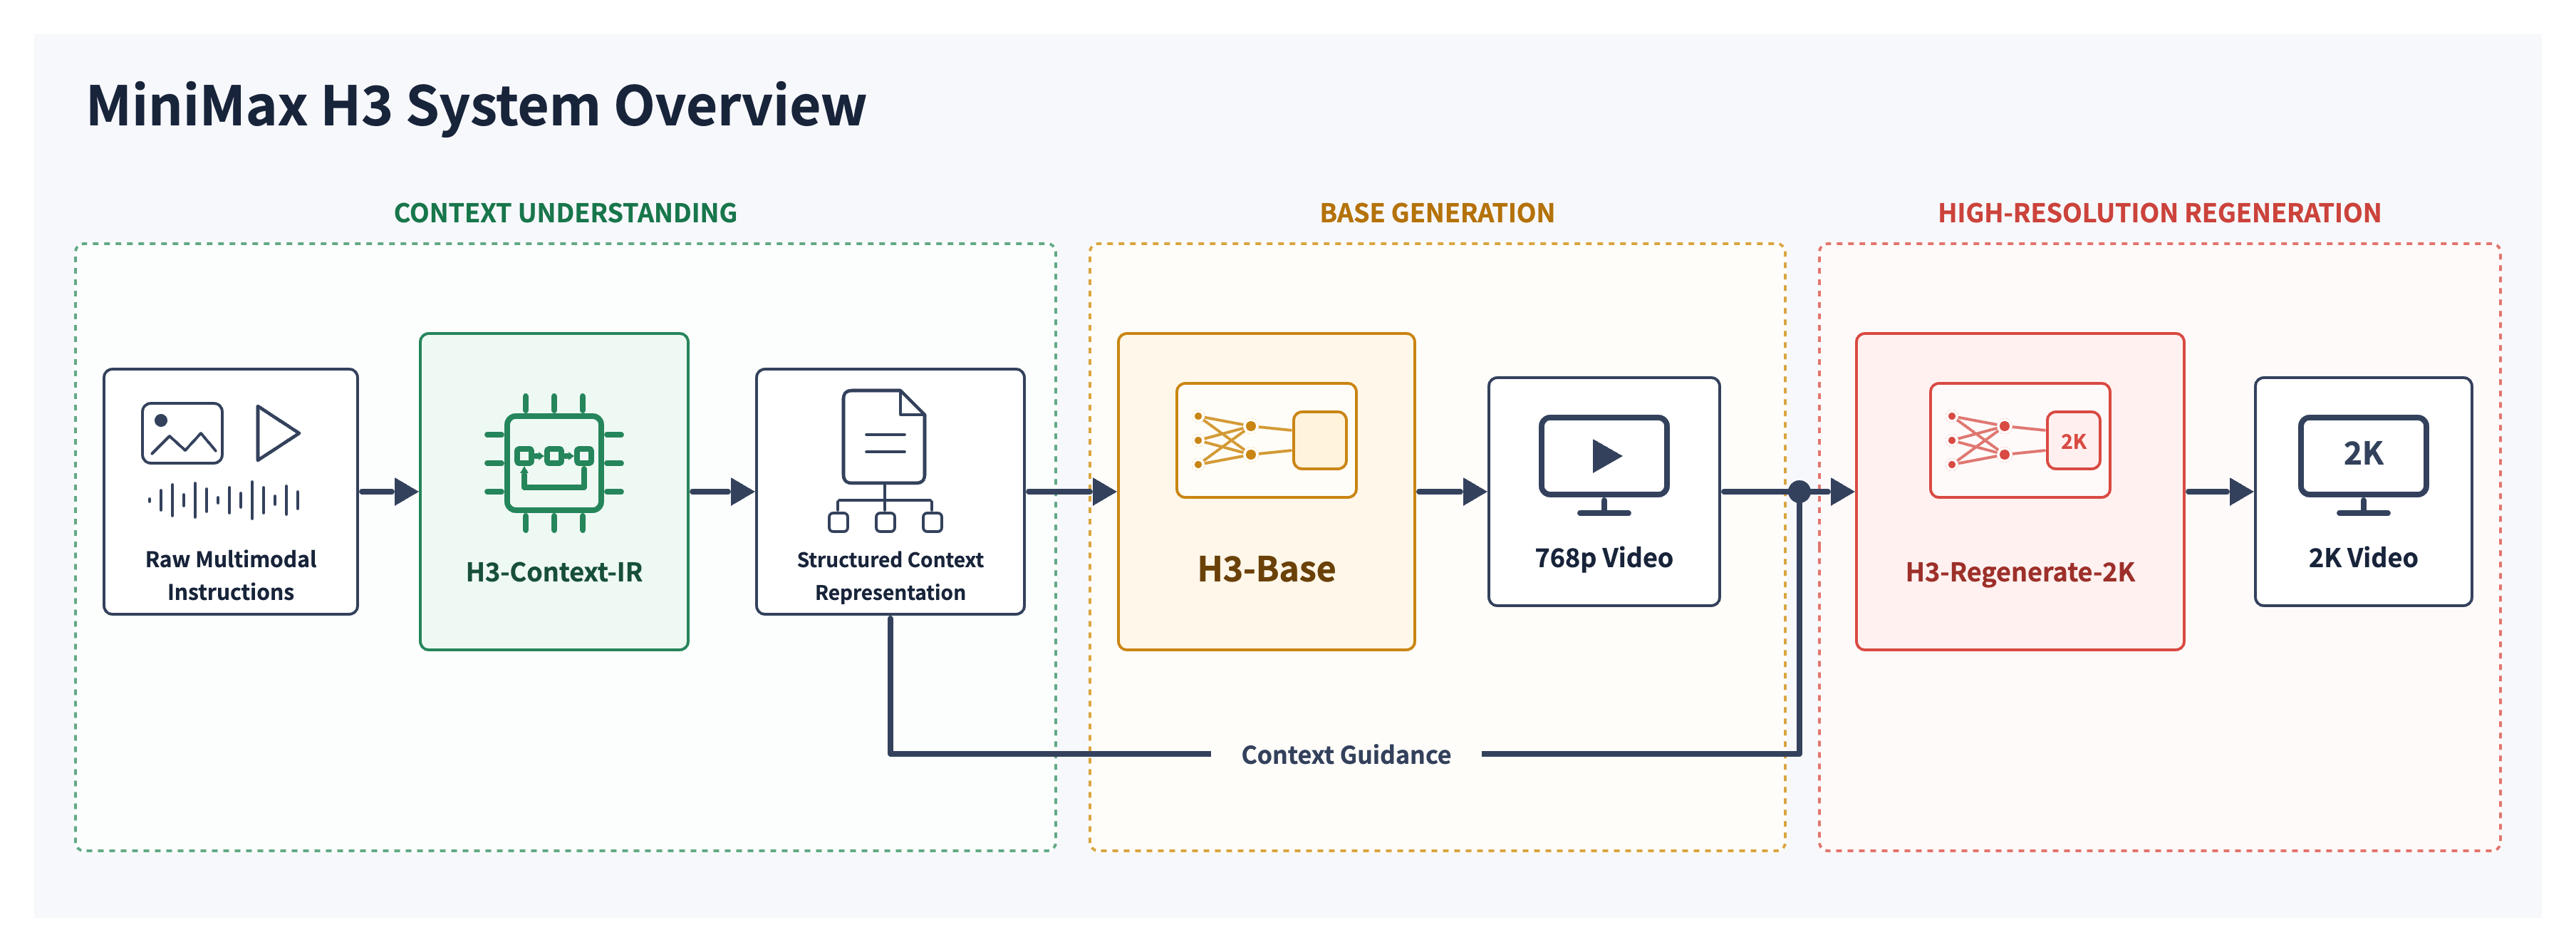
Diagram of the MiniMax H3 three-stage pipeline: context understanding, base generation at 768p, and in-context regeneration to 2K

MiniMax H3: The Open-Weight Video Model That Follows Complex Prompts

MiniMax H3’s real differentiator is instruction following: a 32B Qwen3-VL text encoder, a structured prompt system with shot lists and soundscapes, and 25-second ComfyUI generations. Full breakdown with official demo clips.

August 11, 2026 · 11 min · 2277 words · Marco
A watercolor Art Deco style illustration of a traveler on a cliff gazing at towering clouds, generated with Krea 2

Krea 2 Is the Open-Weights Image Model Worth Running Locally

Krea 2’s K2 Raw and K2 Turbo open-weights release puts a top-10 Artificial Analysis model on consumer GPUs for free. Specs, local ComfyUI setup, Civitai community samples, and what the team said in their AMA.

June 29, 2026 · 8 min · 1557 words · Marco
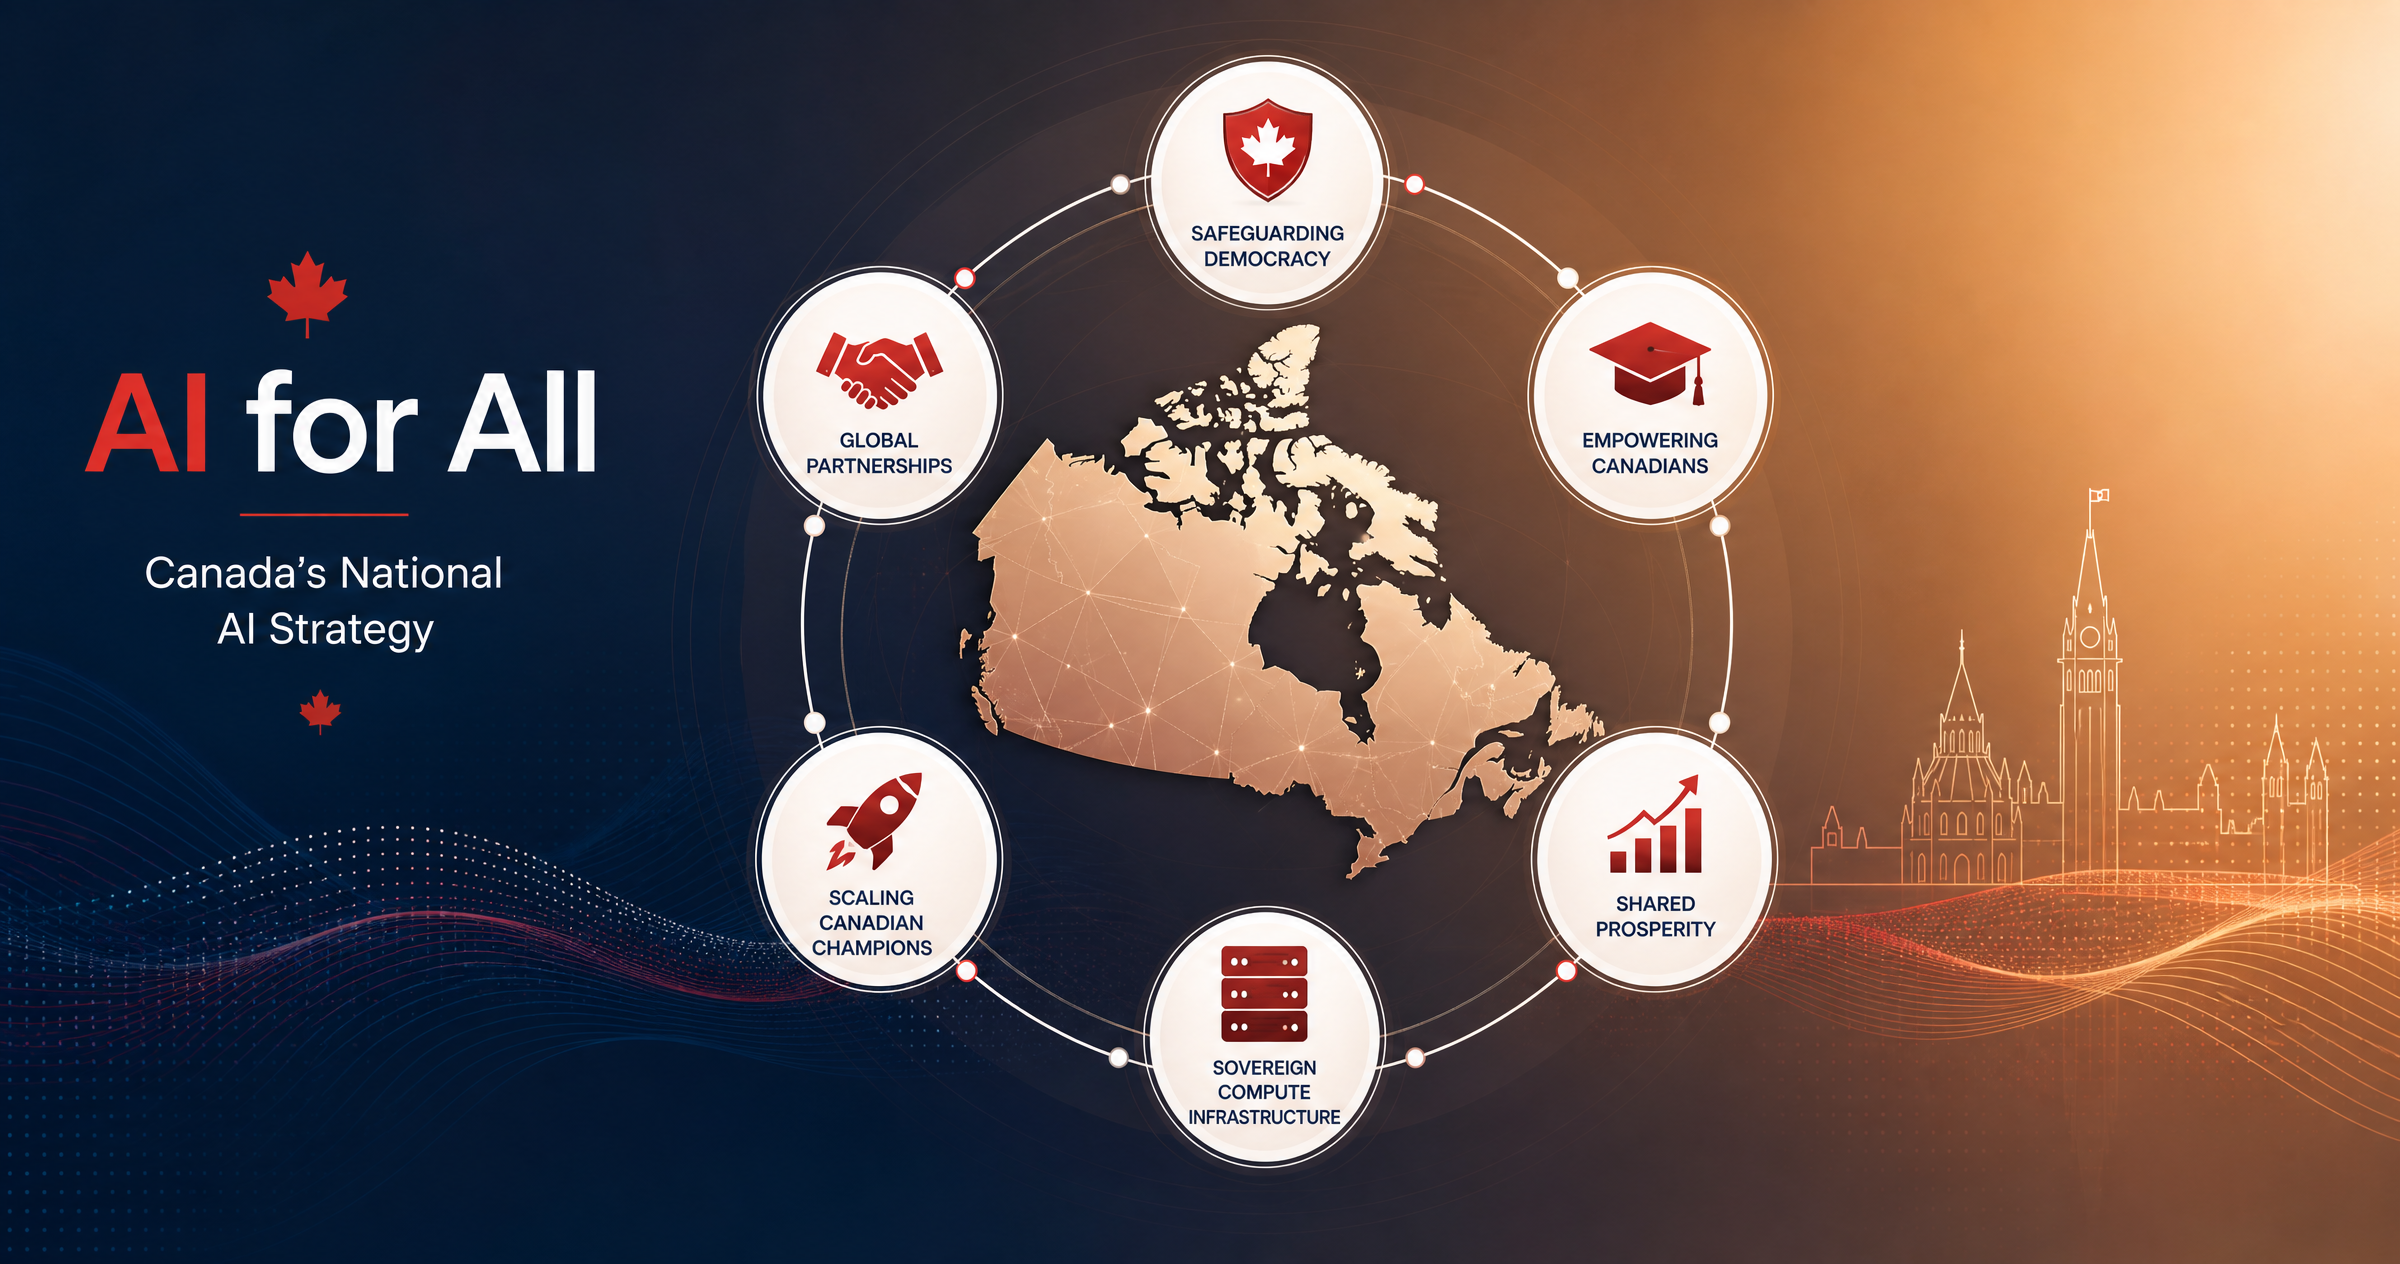
Canada's AI for All strategy — six pillars visual

Canada's AI for All Strategy: A $200B Bet on Sovereign AI

Canada’s AI for All strategy aims to transform the country from an AI innovator with a 12% business adoption rate to a sovereign AI leader targeting 60% adoption by 2034, unlocking $200B in GDP gains, creating 250,000+ jobs, and building sovereign compute infrastructure anchored by a world-leading supercomputer.

June 4, 2026 · 18 min · 3683 words · Marco

Hermes Agent Is Taking Off: A Plain-English Setup Guide

Hermes Agent is gaining attention because it remembers, runs from messaging apps, uses tools, creates reusable skills, and can be self-hosted. This guide explains the rise in plain English and how to approach setup safely.

May 26, 2026 · 10 min · 1980 words · Marco
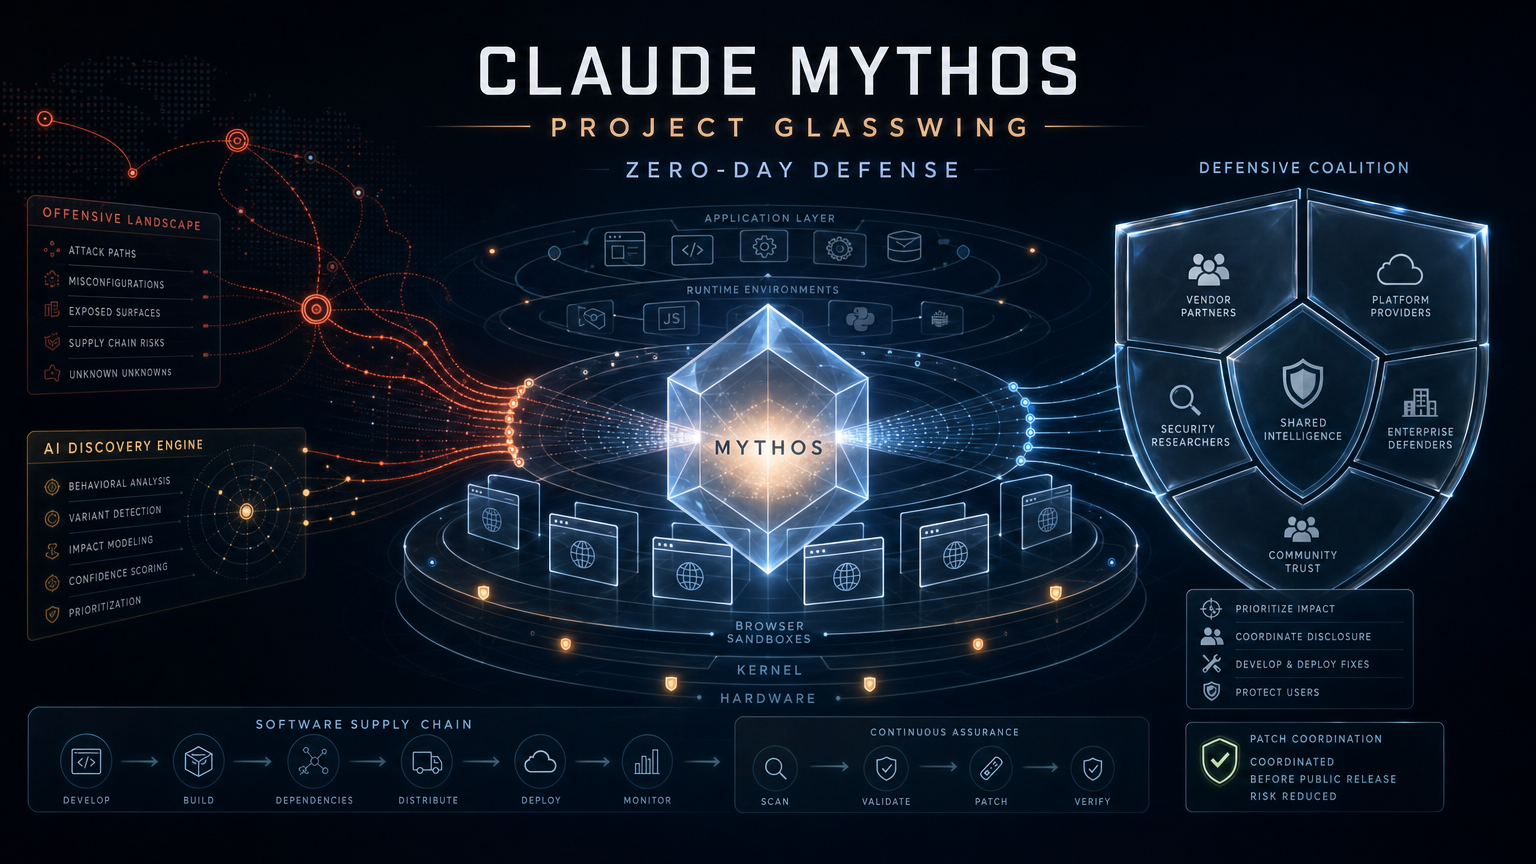
Editorial illustration of Claude Mythos as a glass AI security model surrounded by software infrastructure, zero-day defense signals, and Project Glasswing coordination.

Claude Mythos and the AI Cybersecurity Threshold

Anthropic’s Claude Mythos Preview and Project Glasswing show how frontier AI is shifting cybersecurity from human-limited audits toward AI-scale vulnerability discovery, disclosure, and patching.

May 21, 2026 · 9 min · 1858 words · Marco
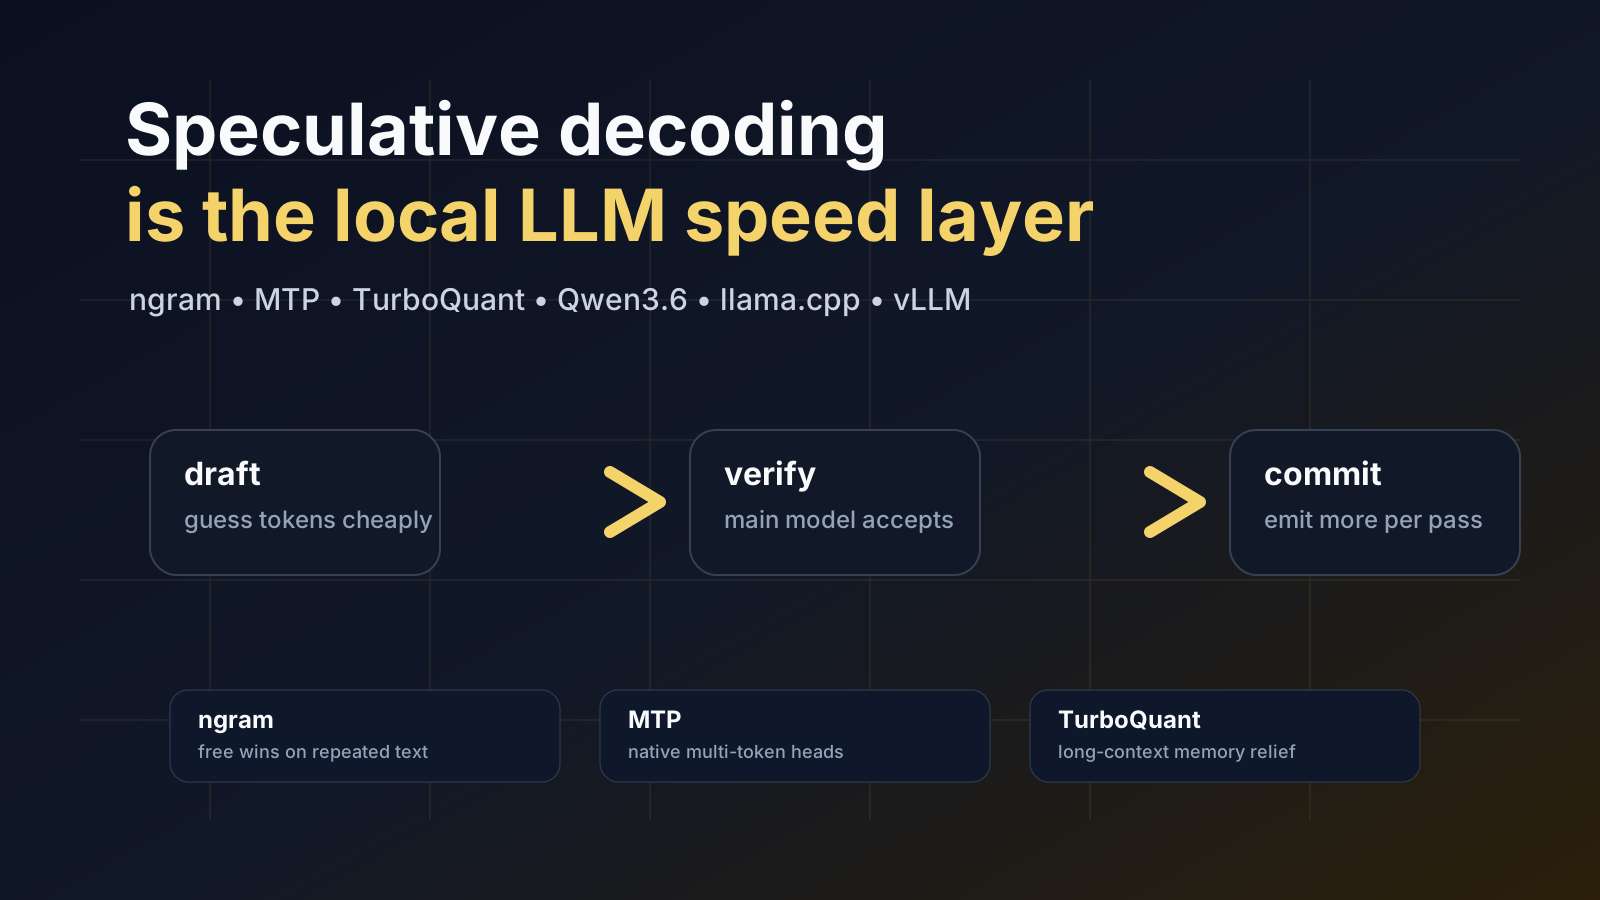
Speculative decoding pipeline showing draft, verify, and commit stages for local LLM inference

Speculative Decoding Is Finally Useful for Local LLMs

Speculative decoding has moved from inference-paper trivia into the local LLM hot path. The useful version now includes ngram speculation, native MTP heads, DFlash-style drafting, and TurboQuant / TCQ KV compression, with early llama.cpp forks showing both real speedups and real rough edges.

May 7, 2026 · 16 min · 3279 words · Marco
Editorial illustration of an AI memory architecture with folders, graphs, vectors, and timelines

Agent Memory Systems in 2026: What Actually Matters

Agent memory is no longer one feature. It has split into several design camps: raw recall, profile memory, context filesystems, reflective memory, coding-agent memory, and enterprise context APIs. This guide maps the trade-offs, the real architectures, and the hype gap.

April 16, 2026 · 19 min · 4028 words · Marco